In a release posted October 14, IBM reported that 80% of executives surveyed at large organizations across eight European and Middle Eastern countries said an AI-related incident had reached their board or C-suite in the past year. The immediate leadership question is what happens after the briefing. Who decides the matter is resolved, and on what evidence? [1]
Censuswide conducted the IBM-commissioned survey among 3,221 executive management respondents at organizations with at least 1,000 employees. These are self-reports, not audited incident records. They do not establish how severe the incidents were or whether responses were effective. Still, the announcement offers a timely reason to examine the last page of an incident report: the part that explains what changed. [1]
The meeting ends. The problem may not.
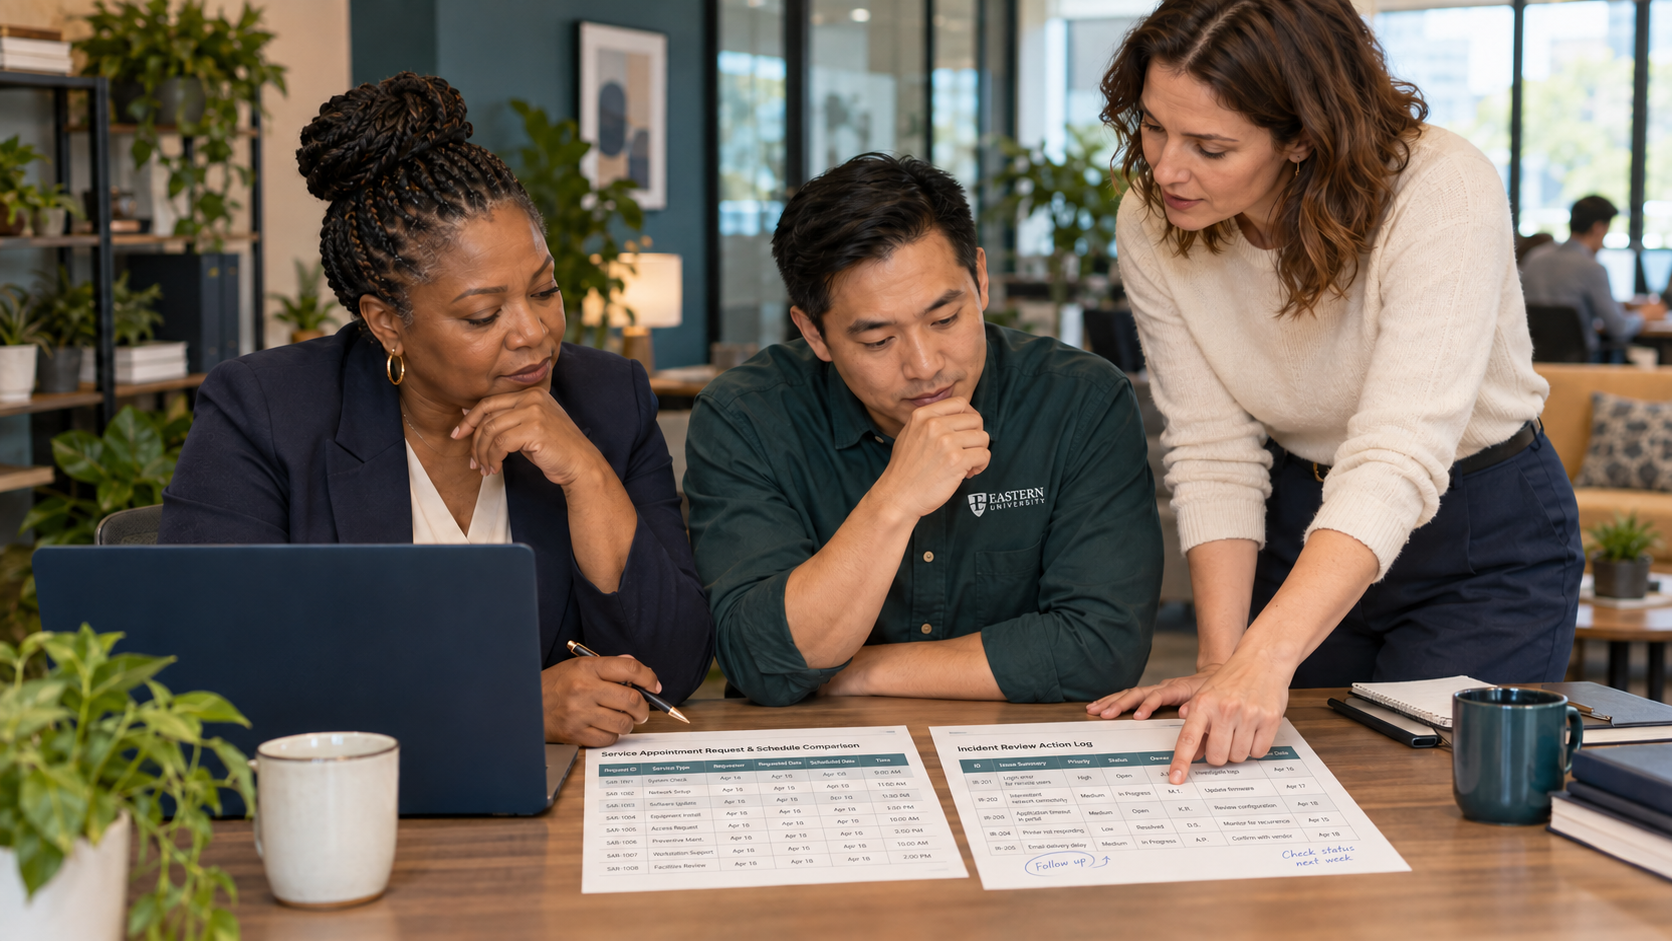
Consider a hypothetical home-services company using AI to help route appointment requests. A customer writes that a technician must arrive after noon. The request is summarized incorrectly, the scheduling team uses that summary, and a morning appointment is booked. The customer complains. A supervisor corrects the booking and the operations director receives a reassuring update: the customer has been contacted.
That resolves one immediate problem. It leaves another question open. Did the error begin in the summary, in the scheduling handoff, or in the way staff were expected to check customer constraints? Replacing the model would be an expensive guess if the handoff remained the problem. Reminding everyone to be careful would be a cheap guess with excellent meeting-room acoustics.
The company needs enough evidence to distinguish those explanations. In this fictional case, I would ask the team to compare the original request, the generated summary and the booking record, using authorized access and appropriate privacy protections. The purpose is to understand the sequence before choosing the remedy. [3]
Give the report a job beyond notification
External research supports that distinction. In a paper published in the AAAI proceedings on March 14, Kevin Wei and Lennart Heim examine incident-reporting design through a literature review and nine safety-critical industry case studies. They describe investigation, analysis, intervention and monitoring as work that must follow reporting, while noting that this learning process remains immature in AI. Their focus is institutional design, not a tested corporate closure procedure. [2]
My application is to separate three decisions in the executive review: what must be contained now, what needs investigation, and what evidence will support closing the follow-up work. Different people may own those decisions. The operating executive should be able to see how they connect.
For the appointment team, correcting the customer's booking is containment. Establishing how the constraint disappeared is investigation. Checking that a revised handoff preserves important constraints is part of deciding whether the corrective action is adequate. Calling all three steps resolved at once would hide unfinished work.
There is a reason to resist premature certainty. A July 6 preprint by Harleen Kaur Sidhu and colleagues distinguishes analysis of an individual incident from analysis across incidents. It also discusses missing context, privacy concerns and uncertainty in reports. Its proposed principles and templates are starting points, not adopted standards or demonstrated fixes. [3]
Applied here, an honest report can say that the cause is still being investigated. Give that uncertainty an owner and a next review point. The alternative is a confident explanation that the next incident may contradict.
A policy edit is not the only useful change
IBM's release says 40% of the organizations whose executives reported escalation cited a change to AI governance policy or framework in response. That finding should not become a claim that the others did nothing. A repaired integration, a narrower use case or a better review process could matter without a rewritten policy. The survey release does not settle that question. [1]
The useful management standard is therefore a justified response. If investigation shows the existing control worked as intended and contained a near miss, leadership may retain it while documenting the reasoning. If the control failed, the response should address the failure. Counting new policies would reward paperwork without telling us whether the next customer is better protected.
There is a relevant lesson in the UK National Cyber Security Centre's rebuild guidance, published July 28 and reviewed October 1. It recommends learning from failed assumptions and allowing those lessons to inform plans and investment, while cautioning against overloading recovery with a full transformation. This is guidance for disruptive cyber attacks. Applying its principle of proportionate improvement to an AI workflow is my interpretation. [4]
For the fictional service company, the response might be a clearer display of customer constraints and a required check before booking. That proposal would still need testing. If it creates so much friction that staff bypass it, the organization has designed another problem into the repair.
Buy evidence before buying a bigger solution
The same distinction should shape investment. Before approving a broad platform replacement because of one incident, ask which failure the proposed purchase addresses and what evidence would demonstrate improvement. Include the work required to operate the remedy. In our scenario, a useful comparison would include staff review effort, missed appointment constraints and corrections, rather than the number of summaries produced.
NCSC's business-continuity guidance, published October 1, recommends exercising plans to expose gaps and test assumptions, and distinguishes tabletop decisions from technical recovery testing. It does not validate an AI appointment workflow. I would adapt that testing discipline to a small, controlled check of the proposed correction before relying on it in live service. [5]
For the next executive review, I would request three short answers. These are proposed management applications of the research and guidance, not an experimentally validated method: [2][3][4][5]
- What do we know? State the affected outcome, the supported explanation and the unresolved questions. Keep a corrected customer case separate from a corrected system.
- What are we changing? Name the owner, the scope and the resources required. Explain why the response fits the evidence, including any reason to retain the current approach.
- How will we know? Test relevant failure conditions with safe examples, inspect the results and set a follow-up review. Record what would justify closure and what would reopen the issue.
Close the loop with a decision
Return to the appointment team. A useful executive update would explain the evidence, the correction and its observed limits. It would identify any work still open. The director could then accept the response, request another test or restrict the workflow while uncertainty remains.
That decision is more informative than a green status box. IBM's survey puts incidents in the boardroom. The leadership opportunity is to make the next conversation about what the organization learned and what it can now justify doing differently.
Questions for executives
- What evidence allowed us to close our last AI incident?
- Which unresolved cause or corrective action still needs an owner?
- Would our proposed investment address the observed failure, and how would we test that?
Sources and further reading
- IBM Study: Eight in Ten EMEA Enterprises Escalate AI Incidents to Board or C-Suite as AI Agents Test GovernanceIBM · Posted; body dateline October 15, 2026 2026-10-14
- Designing Incident Reporting Systems for Harms from General-Purpose AIKevin Wei and Lennart Heim, Proceedings of the AAAI Conference on Artificial Intelligence, 40(44), 38016-38029 · Published 2026-03-14
- Open Problems in AI Incident GovernanceHarleen Kaur Sidhu and colleagues, arXiv:2607.05163v1 · Submitted, version 1 2026-07-06
- Recovering from a highly disruptive cyber attack: 3. RebuildUK National Cyber Security Centre · Published; reviewed October 1, 2026 2026-07-28
- Preparing for highly disruptive cyber incidents: 1. Prepare your business continuityUK National Cyber Security Centre · Published and reviewed 2026-10-01